Choosing the right comparable stores is essential to retail benchmarking that supports sound business decisions. Similar sales alone do not make two stores comparable.
They may operate in different markets, serve different customers, or face different cost pressures. A useful peer group reflects the conditions behind performance.
For business evaluators, those conditions include store format, location, customer profile, product mix, and operating model. This guide shows how to build and test a defensible comparison.
Start with the decision, not the store list
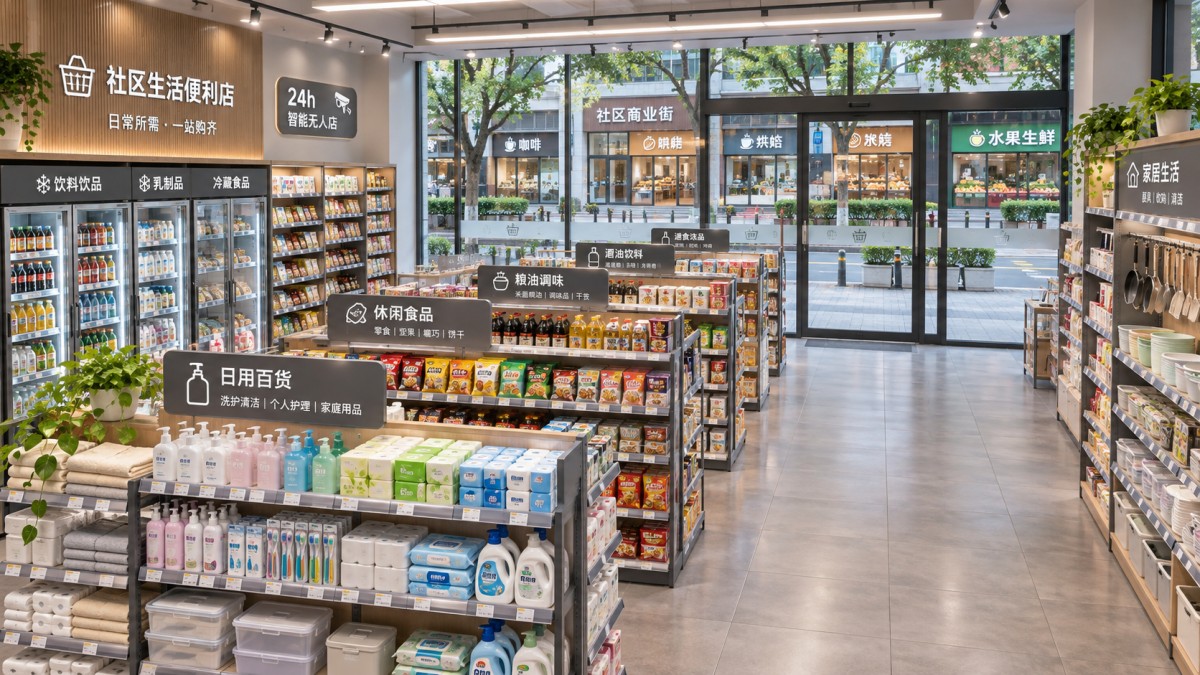
The best comparable stores depend on the question being asked. A peer group suitable for evaluating labor productivity may be unsuitable for assessing lease costs.
Before selecting stores, define the decision, the performance measure, and the period under review. Then identify which operating differences could materially affect that measure.
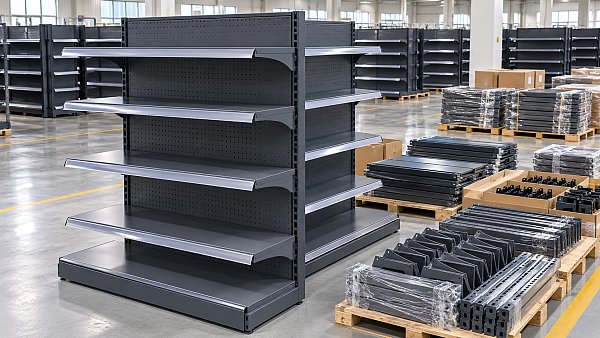
For example, an evaluator assessing a fixture upgrade needs peers with similar layouts, product categories, and customer traffic. Lease terms may be less important for that question.
For a site acquisition, local demand, occupancy costs, and competition deserve greater weight. Technology similarities matter only when they materially influence expected sales or operating costs.
Write down the comparison’s purpose before reviewing candidates. This prevents the analysis from drifting toward stores that are convenient to find but poorly matched.
Which factors make stores genuinely comparable?
No two stores are identical. The goal is to identify differences that could explain performance, then exclude, adjust for, or disclose those differences.
Store format and selling space
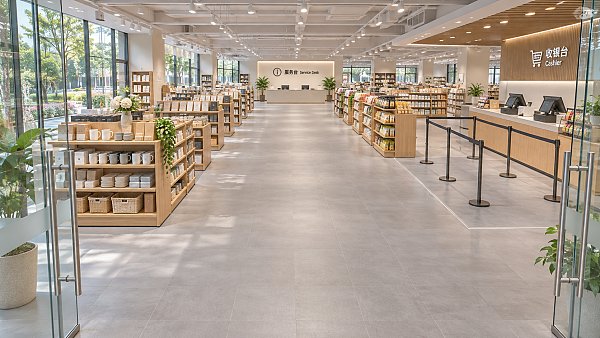
Compare stores with similar formats, such as supermarkets, specialty retailers, department stores, or convenience outlets. Different formats have distinct visit patterns, margins, and staffing needs.
Measure selling area consistently, excluding storage and offices where possible. A large backroom can distort sales-per-square-foot comparisons if one dataset uses total leased space.
Layout also matters. A compact store with high-density shelving may generate different sales and replenishment costs from an experiential showroom of the same size.
Location and customer demand
Assess whether each store serves a downtown, suburban, travel, neighborhood, or destination-shopping market. Footfall and purchasing behavior can differ substantially across these locations.
Review the trade area, customer demographics, local competition, tourism, and accessibility. Use actual customer-origin data where available instead of assuming identical geographic catchments.
For cross-market comparisons, consider purchasing power, currency effects, wages, taxes, and shopping habits. These factors may require adjustment or a separate peer group.
Product mix and price position
Match stores by category mix, price tier, and breadth of assortment. A premium beauty store and a discount household-goods outlet should not share margin targets.
Even within one category, services, private-label products, and promotional intensity can change average transaction value and gross margin. Record these differences before interpreting results.
Operating model and maturity
Check opening hours, staffing model, ownership structure, fulfillment services, and technology. A store handling online pickups may need more labor than its sales suggest.
Store age matters too. Recently opened, relocated, or renovated locations may have temporary traffic and costs that make comparisons with mature stores misleading.
Lease structures and service contracts also affect profitability. Compare controllable store costs separately from corporate allocations when evaluating local management performance.
How to build a defensible peer group
Use a repeatable selection process, and keep a record of excluded stores. The objective is not perfect similarity, but a group fit for the decision.
- Define the scope. Identify the target store, business question, reporting period, and primary metric. Specify whether the comparison supports investment, operations, or valuation.
- Set eligibility rules. Exclude stores with incompatible formats, materially different product categories, unreliable data, or exceptional disruptions during the review period.
- Rank the remaining candidates. Score material attributes such as selling area, market type, customer profile, and operating model against the target store.
- Review the distribution. Check whether the group includes a reasonable range of performance and whether a few stores dominate the results.
- Document the outcome. Record selection criteria, data sources, exclusions, adjustments, and limitations so another evaluator can reproduce the analysis.
Weight the factors according to the decision. Similar traffic and product mix may carry more weight for conversion analysis; wages and opening hours matter more for labor productivity.
A scoring model can help organize judgment, but it should not conceal a critical mismatch. Use mandatory eligibility rules for attributes that cannot be reasonably adjusted.
For example, a candidate with similar size and sales but a fundamentally different fulfillment model may score well overall while remaining unsuitable for staffing comparisons.
How many comparable stores do you need?
There is no universally correct peer-group size. A larger group can reduce dependence on individual stores, but only if its members remain relevant and consistently measured.
Where internal data permits, begin with several credible peers and examine how the result changes when individual stores are removed. Treat very small samples cautiously.
If one store’s inclusion changes the benchmark substantially, investigate why. The difference may reflect an unusual operating condition, a data error, or an overly broad group.
When close matches are scarce, present a narrow primary group alongside a broader reference group. Label the latter as context, not an equivalent performance target.
Do not combine materially different formats merely to increase the count. A transparent range with known limitations is more useful than a precise but misleading average.
Which metrics should you compare?
Choose a small set of measures linked to the decision, then confirm that every store uses the same definitions, time period, and accounting treatment.
- Sales per selling-area unit: Useful for assessing space productivity, provided selling area and sales recognition are defined consistently.
- Conversion rate: Transactions divided by visits; useful for evaluating merchandising or service when traffic counters measure visits comparably.
- Average transaction value: Net sales divided by transactions; interpret alongside price position, product mix, promotions, and returns.
- Gross margin rate: Gross profit divided by net sales; check treatment of markdowns, freight, supplier allowances, and inventory adjustments.
- Sales per labor hour: Net sales divided by relevant paid hours; include fulfillment and other activities consistently across stores.
- Occupancy cost ratio: Comparable occupancy costs divided by net sales; review rent, service charges, taxes, and lease incentives separately.
Use medians and ranges alongside averages when data permits. They help show typical performance and dispersion, although even a median can mislead in a tiny sample.
Compare like periods, including seasonal peaks and promotional events. A full-year comparison may hide a specific operational issue that appears only during high-demand weeks.
For omnichannel retailers, agree how pickup orders, returns, and ship-from-store transactions are attributed. Otherwise, the same activity can inflate one location and depress another.
What should you do when the data is incomplete?
Internal stores often provide the most consistent operational data, but they may share company-specific practices that limit the comparison. External peers add context but require verification.
Public reports, industry studies, landlord information, and commercial datasets can help identify candidates. Check each source’s coverage, reporting date, definitions, and permitted use.
Separate observed values from estimates. For each important metric, record its source, collection period, completeness, and any assumptions used to make it comparable.
When data is missing, avoid treating an unknown value as a match. Seek corroboration, use a documented proxy, or exclude that metric from the comparison.
Normalize only where the method is defensible. For instance, converting currencies can aid reporting, but exchange rates alone do not remove differences in local purchasing power.
Likewise, adjusting labor costs for wage rates may clarify productivity, but it does not automatically account for differences in service levels, regulation, or staffing responsibilities.
Run a sensitivity check on material assumptions. If a reasonable change in estimated selling area reverses the conclusion, report that uncertainty before recommending an investment.
Example: Evaluating a fixture investment
Suppose a retailer is considering new shelving for a mature suburban specialty store. Management wants to know whether the investment could improve space productivity.
The evaluator selects stores with similar selling areas, categories, customer profiles, and traffic patterns. Stores undergoing major renovations or operating primarily as showrooms are excluded.
Within the resulting group, comparable stores using the proposed shelving have median annual sales of $650 per square foot. The target store records $580.
The $70 gap identifies an opportunity for investigation, not a forecast. Better locations, different assortments, or stronger execution may explain some or all of it.
Before approving the project, estimate incremental gross profit under several sales scenarios, then deduct installation, maintenance, disruption, and any additional operating costs.
For illustration, a 2,000-square-foot selling area and a $10-per-square-foot sales increase imply $20,000 in additional annual sales, before considering cannibalization or other effects.
At a 40% incremental gross margin, that is $8,000 before incremental costs. Compare the resulting cash flows with the investment and the company’s required return.
A pilot with a suitable control group can strengthen the decision. Track comparable pre- and post-installation periods, and monitor changes in traffic, assortment, and promotions.
How to turn the benchmark into a decision
Start by separating the observed gap from its possible causes. A store below its peers may face weaker demand, higher costs, operational constraints, or measurement differences.
Investigate the largest plausible drivers before assigning targets. Store visits, transaction data, staff interviews, and category-level results can reveal conditions that aggregate figures miss.
Prioritize actions by expected financial impact, implementation cost, confidence, and operational risk. A measurable process improvement may be preferable to a costly redesign with uncertain returns.
When evaluating fixtures, lighting, or retail technology, compare specifications and total costs as well as performance. Relevant safety and performance requirements vary by product and market.
Document the decision owner, baseline, review date, and success measures. Refresh the peer group when store formats, local conditions, or reporting definitions materially change.
Conclusion
Effective retail benchmarking begins with a specific decision and a peer group matched to the factors that influence it. Similar sales alone are insufficient.
Use consistent metrics, disclose imperfect data, and test whether conclusions survive reasonable changes in assumptions. Treat performance gaps as questions to investigate, not guaranteed returns.
A defensible comparison gives business evaluators a clearer basis for prioritizing investments, setting realistic targets, and identifying which improvements warrant further evidence.